Laya developers report 32.8ms decisions from an AI model that doesn't generate text
Laya's developers describe an open-weight AI model family that returns structured decisions rather than generated text, reporting 32.8-millisecond inference on a single GPU. The project targets tasks such as email triage and support routing, but its own tests underscore important limits: performance depends on language routing, task-specific training and calibration.
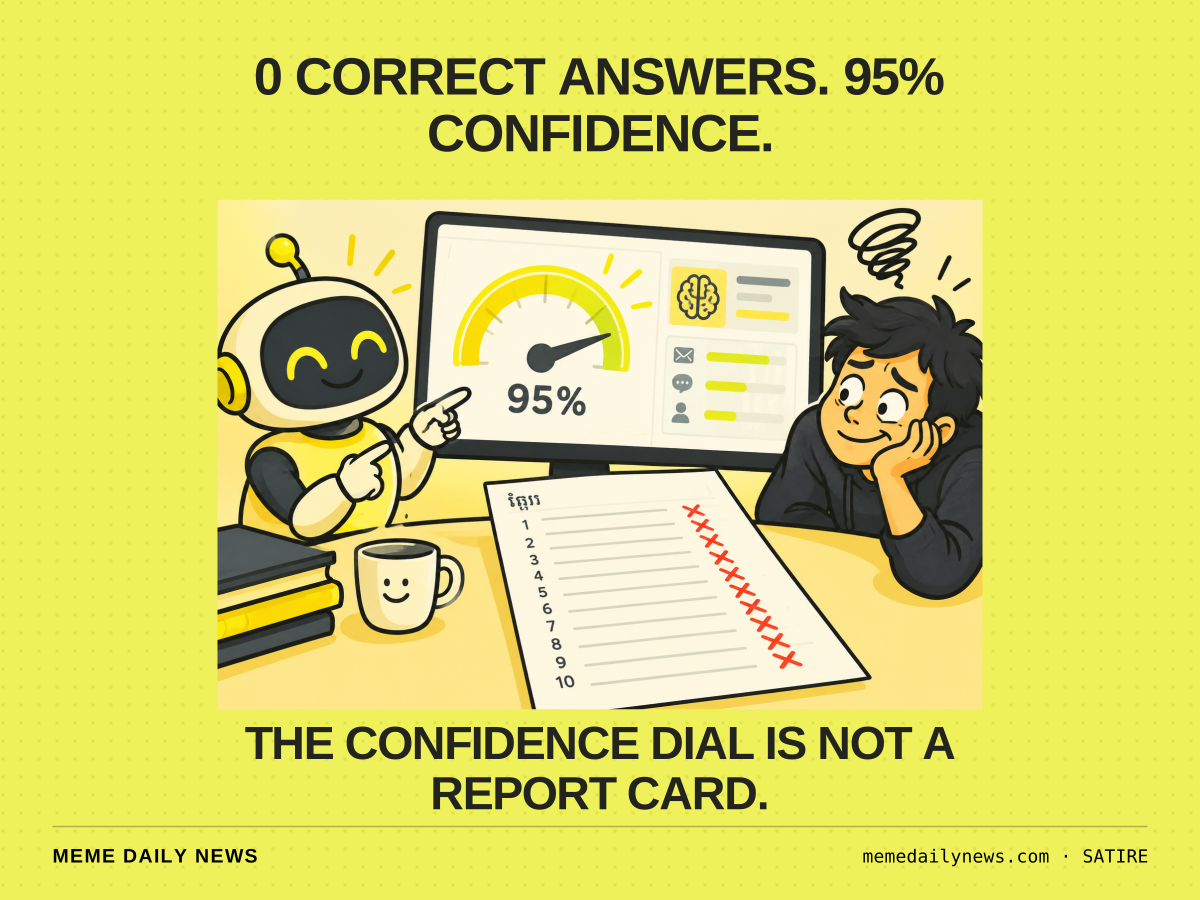
The actual story.
The supplied project write-up is undated and describes earlier research from March 2025 and a competitor launch in September 2026; it does not establish Laya's release date. Developers describe English, multilingual and specialized decision checkpoints with Apache 2.0 weights. Their reported 0.766 typed-decisions accuracy follows benchmark-specific fine-tuning; base models score around 0.35. They also report that the English checkpoint answered none of 100 Khmer questions correctly while averaging 0.952 confidence, motivating language routing before inference. Calibration requires domain-specific adjustment, and performance degrades with large option sets. These are developer-reported findings, not independently verified comparisons. Structured numeric output should not be confused with guaranteed correct decisions.
Laya makes a case for small, specialized decision models—but its own results show that fast, structured answers still need language routing, calibration and task-specific testing.
Receipts, not rumors.
Read the original reporting: Hacker News ↗
The reporting above provides context. The meme is satire. This story was produced and published automatically from the linked source.
Got a better punchline?