Grok Bot vs. dots vs. Muse: The Tests Disagree
Dots leads two completion benchmarks, Muse tops another scorecard, and some hands-on reviewers prefer Grok. The differences become clearer when you look at the work being tested.

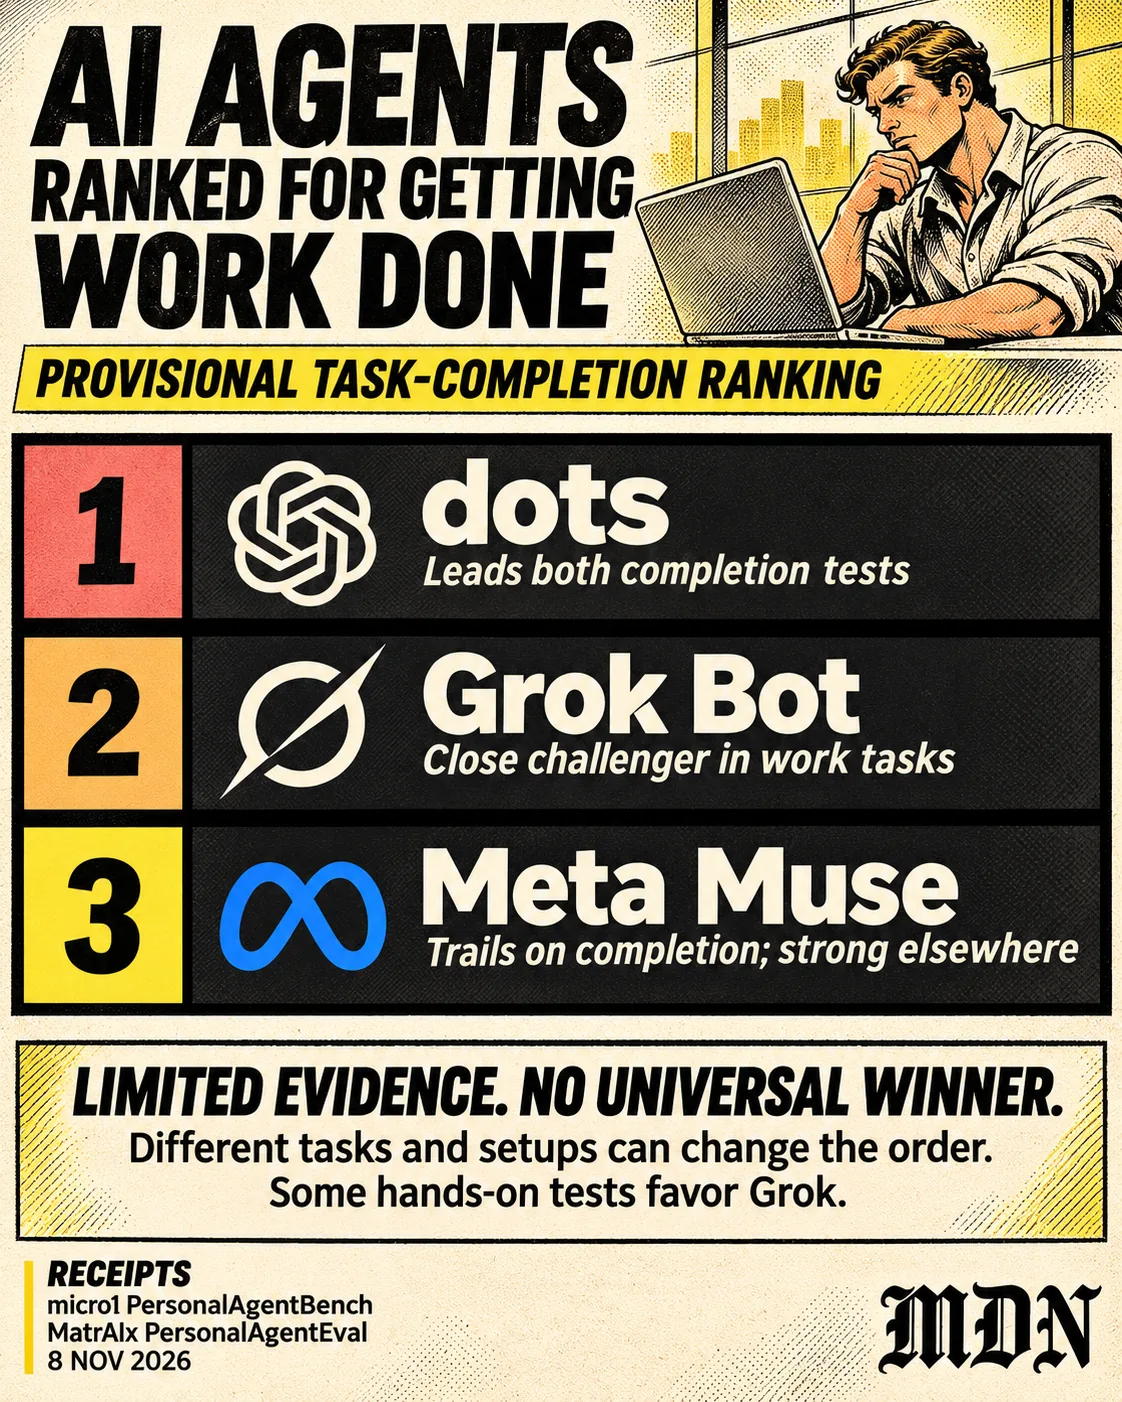
The early tests of xAI’s Grok Bot, OpenAI’s dots and Meta’s Muse produce different winners. Completion-focused benchmarks favor dots among these three. A broader rating system puts Muse first, while hands-on reviewers report stronger results from Grok on some business tasks.
MDN’s provisional ordering for accuracy-focused task completion is 1. dots, 2. Grok Bot, 3. Meta Muse. That is an editorial reading of published evidence, not a new head-to-head test or an industry consensus.
Where dots leads
micro1’s PersonalAgentBench tested 20 tasks per assistant across work involving tools such as Gmail, Calendar and Drive. Dots scored 80%, Grok Bot 65% and Muse 55% on both task completion and trusted completion, which also checks that the result meets the task’s requirements without disqualifying mistakes.
Those results are useful, but narrow. The evaluation used the first eligible run, a small task set and nonidentical prompts, accounts and conversation histories. It cannot establish how reliably each product will perform across every kind of work.
PersonalAgentEval’s leaderboard also places dots above Grok and Muse in its published completion results. Its methodology combines standalone requests with linked, multistep scenarios using personal-account context and hidden requirements. It compares complete assistant setups, and the published methodology does not establish repeat-run reliability. Scores from the two benchmarks should not be averaged: their tasks, scoring units and success criteria differ.
Why Muse tops another scorecard
Assistant Benchmark ranks Muse at 9.3, Grok at 8.8 and dots at 8.6. These are ratings out of 10, not percentages of successfully completed tasks.
The site evaluates dimensions including research, creativity and personal-assistant work. Its methodology uses published tasks and evaluator judgments, with different tested coverage across assistants. That makes it useful for examining strengths, but not interchangeable with a completion benchmark.
Muse’s lead here is a reason to examine the underlying work rather than dismiss the result because it conflicts with another leaderboard.
Where hands-on reviewers favor Grok
In AI for Mortals, Pat Simmons reports Grok winning three comparisons involving travel planning, YouTube research and writing, and a simulated coffee business. Those are concrete examples, although one reviewer’s three jobs cannot establish broad reliability.
Claire Vo’s nine-task comparison favors Grok for broad work, Muse for personal and creative tasks, and dots for coding and Slack-context judgment. The assistants had unequal connectors, memories and operating setups, so this is evidence about the experiences tested rather than a controlled measure of model capability.
How to read the provisional ranking
Dots has the strongest completion-focused evidence in this comparison. Grok remains a credible challenger, especially when the work resembles the business workflows in the hands-on reviews. Muse’s third place on completion does not make it third at every task.
The evidence does not establish a statistically reliable gap or rule out a tie in a particular workflow. These products and their connected tools also change quickly.
For a useful comparison, give each assistant the same job, information, permissions and deadline. Check whether the final result is correct, whether instructions were missed, how much intervention was needed and what it cost. A confident response is only one part of getting the work done.
The early evidence gives dots the strongest case for accuracy-focused task completion, while Grok has a strong showing in hands-on business workflows and Muse stands out for everyday and creative work. The tests disagree, and none establishes a universal winner. Run the work you actually need done with comparable access, then compare correct results, missed instructions, intervention and cost.
Receipts, not rumors.
- micro1 PersonalAgentBench: completion results and methodology
- PersonalAgentEval: published leaderboard
- PersonalAgentEval: methodology and limitations
- Assistant Benchmark: leaderboard
- Assistant Benchmark: dimensions and methodology
- AI for Mortals: three hands-on comparisons
- Claire Vo / How I AI: nine tasks, four agents
- xAI: Grok Bot product information
- OpenAI: Introducing dots
- Meta: Introducing Muse
Read the original reporting: micro1 PersonalAgentBench
The reporting above provides context. Illustrations are editorial interpretations, not source photographs.
What’s your take?